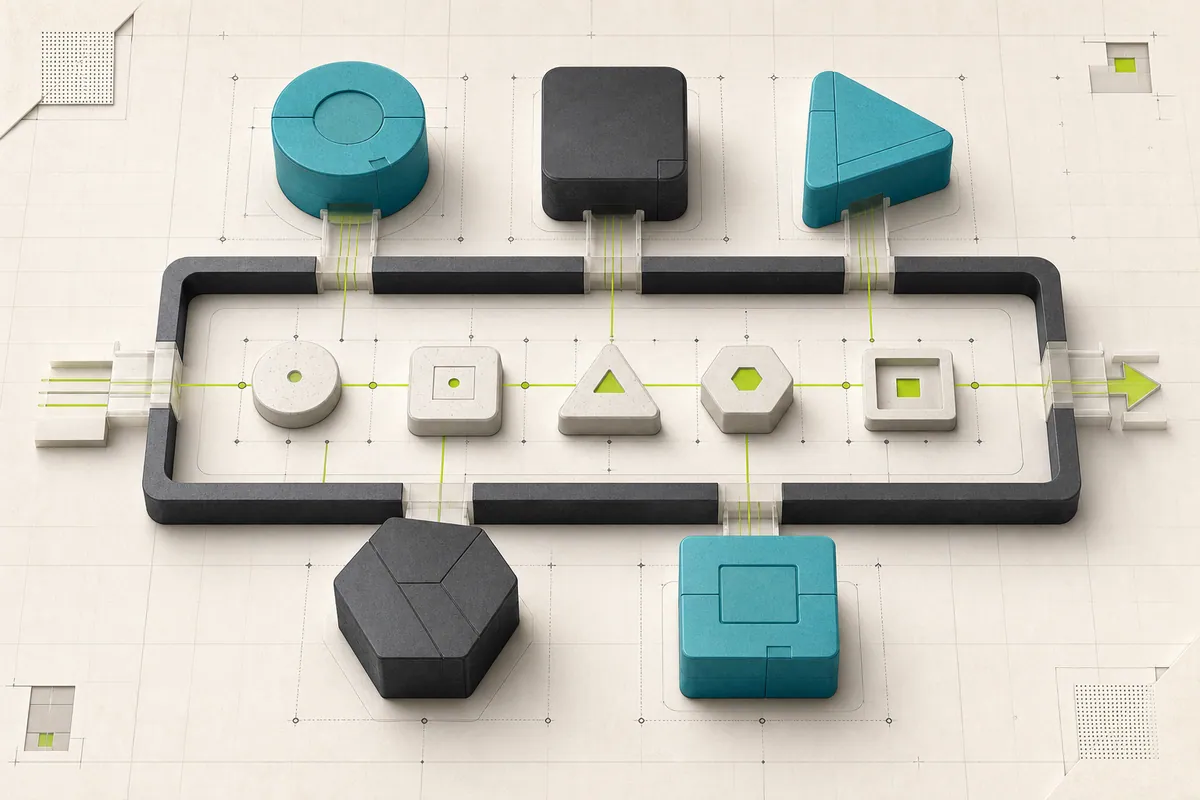
Test the complete workflow with real inputs, not the polished demo task the vendor chose.
Update — August 13, 2026: The checklist now defines a representative test set, severity-based scoring, stop conditions, cost boundaries, and the evidence required for an adoption decision.
AI software can look transformative in a two-minute demonstration and become frustrating in normal work. The difference is usually context: your files are messier, your approvals are slower, and your edge cases are real.
A useful evaluation measures the complete workflow rather than the quality of one generated answer.
The questions worth answering
Run a small, time-boxed test and document the answers with evidence.
- Which repeated task does it replace or shorten?
- How much review does each result require?
- Can company data be used to train external models?
- What happens when the tool is confidently wrong?
- Can data be exported in a usable format?
- Does pricing rise with seats, usage, or both?
Start with risk, not model names
The NIST AI Risk Management Framework organizes work into Govern, Map, Measure, and Manage. For a small-team trial, that translates into four practical questions: who owns the decision, where the tool enters a workflow, how performance and harm will be measured, and what happens when the result is unacceptable.
NIST’s Generative AI Profile adds risks specific to generative systems, including convincing false content, privacy leakage, information security, harmful bias, intellectual-property concerns, and over-reliance on generated output. Not every tool carries every risk; map the ones created by the actual use case.
Build the test set before opening the trial
Select examples from the work the tool is supposed to handle: ordinary cases, incomplete inputs, ambiguous requests, sensitive material represented with approved test data, and failures that would cause real harm. Freeze that set before the vendor demo so every candidate receives the same task and reviewers cannot quietly replace difficult examples with easier ones.
Score by consequence, not only by average quality. A harmless formatting mistake and a fabricated contractual clause should not cancel each other out. For every test, define the expected outcome, unacceptable outcomes, reviewer, allowed data, and maximum correction time.
- Routine cases that represent most weekly volume.
- Edge cases with missing, contradictory, or adversarial inputs.
- A refusal case where the system should stop or ask for clarification.
- A permission case involving data or tools the user should not access.
- A recovery case showing how a bad output is detected, corrected, and recorded.
Measure the boring middle
Do not compare only the time needed to produce a first draft. Include setup, prompting, correction, approval, and delivery. That is the actual cost of the workflow.
A tool that produces a result in seconds can still lose to a reliable template if review takes twenty minutes. Record accepted outputs, material corrections, false claims, reviewer time, and failures by task type. An average score can hide one unacceptable category.
Run a reversible pilot
Choose one workflow, a small user group, representative inputs, and a fixed end date. Remove secrets and personal data unless the contract and configuration explicitly permit them. Keep the old process available while the team learns where the system fails.
At the end, decide to adopt, restrict, extend the trial, or stop. Write the reason. A pilot that quietly becomes permanent avoids the very governance work the pilot was supposed to inform.
- Name a business owner and a technical or security reviewer.
- Define acceptable quality and a maximum review time.
- Document data retention, training, export, and deletion terms.
- Create an escalation path for harmful or confidential output.
- Set the next review date because models and terms change.
Define stop conditions and the buying boundary
Write the conditions that end or restrict the pilot before enthusiasm creates a sunk-cost argument. Examples include an unresolved data-use term, a severe permission failure, a harmful output that escapes the review control, no usable export, or correction time above the existing process. A stopped pilot is a valid result when it prevents an unsafe or uneconomic deployment.
Price the complete operating model: seats, usage, premium models, storage, connectors, security tier, implementation, review labor, monitoring, training, and contract overlap. Compare that annual cost with the measured time or risk reduction in the tested workflow. Do not convert a speculative productivity claim into financial savings.
- Adopt: evidence meets the quality, risk, control, and cost thresholds.
- Restrict: value exists only for named tasks, users, or data classes.
- Extend: the remaining uncertainty has a test and fixed end date.
- Stop: a veto condition occurred or the complete workflow does not improve.
This article explains the practical implications of the primary material below. PatchMemo does not publish vendor copy as editorial coverage and does not accept payment for positive coverage.
PatchMemo independently selects and evaluates the topics it covers. Analysis and recommendations are ours; sources are linked so readers can check the underlying claims. We clearly label sponsorships and affiliate relationships, and neither determines coverage or conclusions.